How to Find and Fix Redirect Chains and Redirect Loops
Trace every redirect hop, diagnose loops across server layers and replace avoidable chains with clean direct routes.
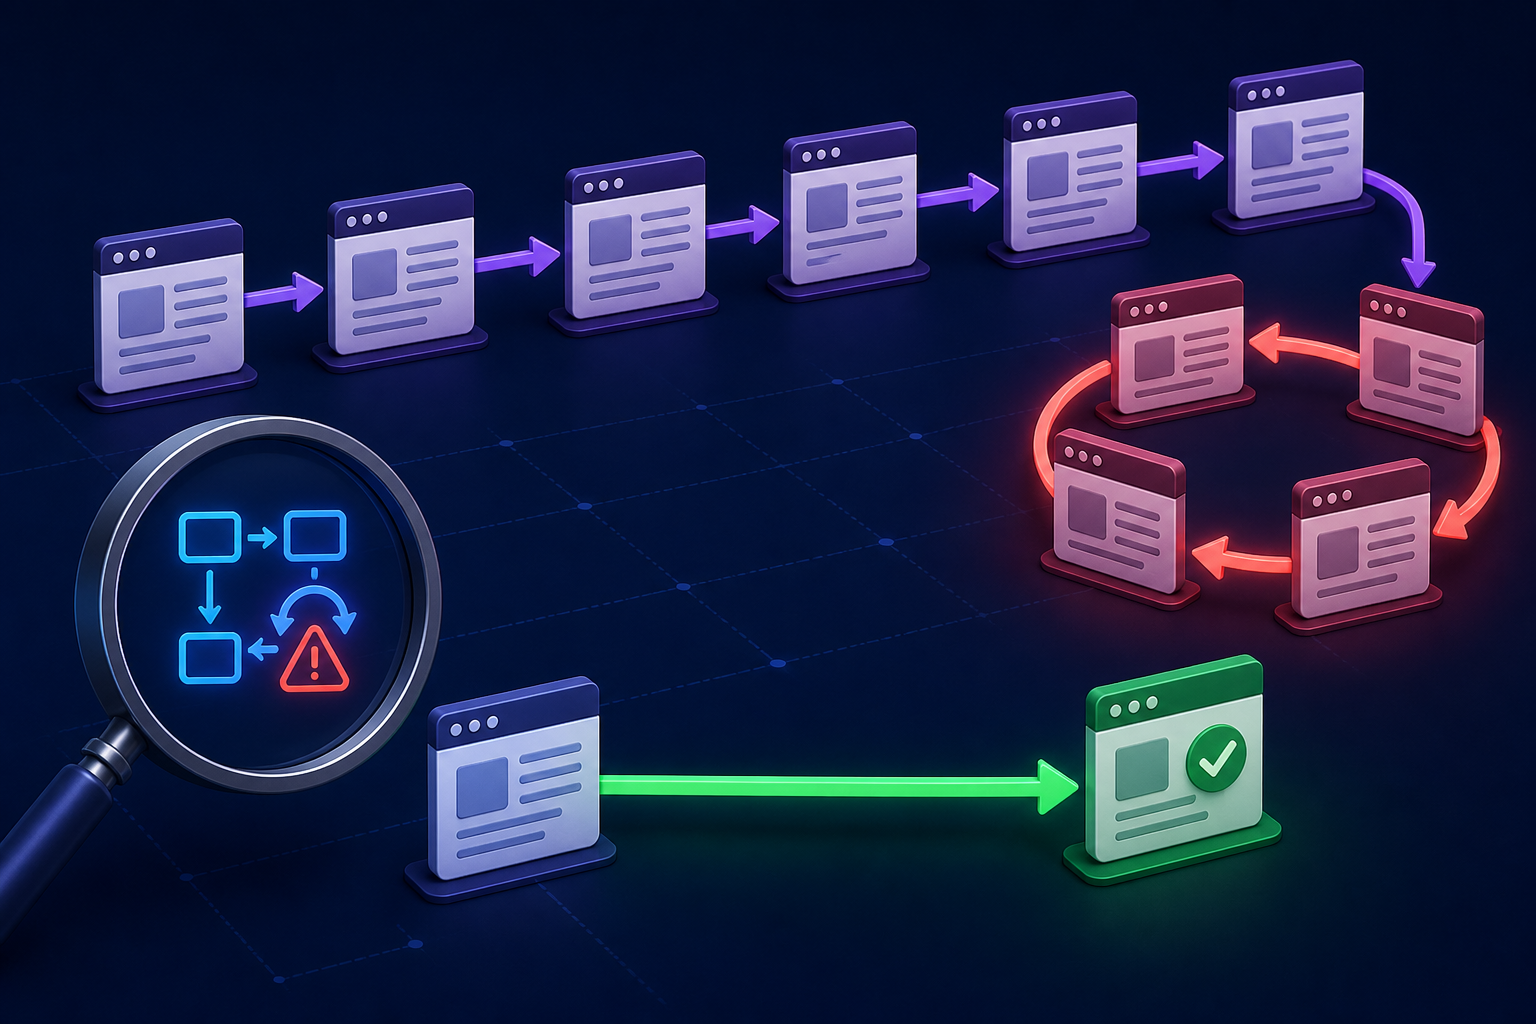
A redirect should normally take a request from an outdated address directly to the final relevant page. Over time, migrations and repeated slug changes can create a chain of intermediate URLs. A configuration mistake can also send the request in a circle, producing a redirect loop and preventing the page from loading at all.
What is a redirect chain?
A chain occurs when one redirect points to another redirect instead of the final page:
/old-guide → /new-guide → /seo-guide → /final-seo-guideThe visitor eventually arrives, but every hop requires another request. Chains add latency, complicate analytics and debugging, waste crawler requests, and increase the chance that one intermediate rule will fail.
What is a redirect loop?
A loop occurs when redirects lead back to a URL already visited:
/page-a → /page-b → /page-aBrowsers stop after a safety limit and display an error such as “too many redirects.” Longer loops can involve hostname, protocol, slash, locale, or authentication rules, which makes the circle less obvious.
Trace every hop
Test the exact starting URL with the free Redirect Checker. Record the status code and Location destination at each step. The final response should normally be a successful canonical page, not another redirect, a server error, a blocked page, or a soft 404.
Do not test only the clean URL you expect visitors to use. Check old backlinks, sitemap history, HTTP, HTTPS, www, non-www, slash variants, uppercase variants, and URLs generated by the application.
Common causes of redirect chains
A page slug changes more than once and every migration adds a new rule.
An HTTP URL redirects to HTTPS and then separately redirects between hostnames.
A CMS plugin and server configuration both normalize trailing slashes.
A language or country redirect runs after the canonical-host redirect.
An external tracking link points to an old internal redirect.
Internal links and sitemaps still use legacy URLs.
Common causes of redirect loops
Conflicting proxy and application HTTPS rules
A reverse proxy terminates HTTPS, but the application believes the incoming request is HTTP and repeatedly redirects it. Configure trusted proxies and forwarded headers correctly.
Opposing www rules
The web server redirects www to non-www while a CDN or application redirects non-www back to www. Select one canonical host and enforce it in one coordinated direction.
Trailing-slash disagreement
One layer adds the slash and another removes it. Align router, web server, CDN, and application conventions.
Cookie or login conditions
A protected route redirects to login, while the login page redirects back because of stale session state or an incorrect authentication check.
How to fix a redirect chain
Choose the single final canonical URL.
Update every legacy rule so it points directly to that final address.
Replace old internal links in navigation, templates, articles, feeds, and structured data.
List only the final URL in XML sitemaps.
Update controllable external links and campaign destinations.
Retest each old entry point without relying on browser cache.
Keep necessary old-to-final redirects. The goal is not to delete migration coverage; it is to remove avoidable intermediate hops.
How to fix a redirect loop
Capture the exact repeating sequence with a redirect trace.
Identify which layer returns each response: CDN, load balancer, server, framework, CMS plugin, or authentication middleware.
Disable or narrow one conflicting rule in a safe environment.
Clear server, CDN, and browser caches where applicable.
Test both anonymous and authenticated requests.
Verify that the final URL returns content without another Location header.
Audit redirects after every migration
Maintain a redirect map containing source, destination, reason, owner, and creation date. Crawl the old URL list before launch and again after deployment. Monitor 404 reports and server logs to discover important legacy addresses that were missing from the map.
Also inspect canonical tags. A final page should not canonicalize back to an old redirected URL. This creates a contradictory loop of signals even when the HTTP request itself loads successfully.
Frequently asked questions
How many redirect hops are acceptable?
A direct single redirect is the clean target. A short unavoidable chain may work, but each extra hop adds delay and another failure point.
Do redirect chains reduce rankings?
They are mainly a performance, crawling, maintenance, and signal-clarity problem. Fix them because direct architecture is faster and more reliable, not because of a promised ranking increase.
Why does the loop happen only on the live website?
Production may add CDN, proxy, HTTPS, caching, hostname, or authentication layers that are absent locally. Trace the live headers and inspect each responsible layer.
Can browser cache preserve an old redirect?
Yes, permanent redirects can be cached. Test with command-line headers, a clean browser profile, or a dedicated checker while also clearing relevant caches.
Should old redirect URLs remain in the sitemap?
No. Sitemaps should list final canonical URLs that return successful indexable responses.